Español
 Português (Brasil)
 Français
 Deutsch
 Italiano
 Nederlands
 Polski
 Svenska
 Türkçe
 Русский
 日本語
 한국어
 简体中文
 Tiếng Việt
 Bahasa Indonesia
 繁體中文
 Čeština
 Dansk
 Norsk (bokmål)
 Suomi
 Ελληνικά
 Română
 Magyar
 Українська
 ไทย
 हिन्दी
 العربية
 עברית
How Recommendation Widgets Choose the Ads You See
The ad you see in a "you may also like" widget wasn't chosen by the highest bidder alone. It won a real-time auction that weighs bid against how likely you specifically are to click it.

A content recommendation widget, the "you may also like" box under an article, decides which ads to show through a real-time auction that ranks eligible creatives by predicted engagement value, not just the highest bid. The network's ad server combines the advertiser's bid with a predicted click-through rate for that specific reader and placement, and whichever combination produces the highest expected revenue for the publisher wins the slot, all in the time it takes the page to load.
Here's the actual sequence, and what determines which specific ad you see versus the person sitting next to you.
The request-to-render sequence#
- You load a publisher page. A script embedded on the page (from Taboola, Outbrain/Teads, MGID, Revcontent, or another network) fires as the page renders.
- The widget requests ads from the network's ad server. This request carries contextual signals: the page's topic and category, your device type, your rough location, and often behavioral signals tied to a cookie or device ID if you've interacted with the network before.
- The ad server runs an auction among eligible campaigns. Every advertiser targeting that geo, device, and context becomes a candidate. This is the native ad auction, and it happens in milliseconds.
- Each candidate ad gets ranked, not just by bid, but by bid multiplied by a predicted click-through rate for that specific user and context. This is why a lower bidder with a highly relevant, high-CTR creative can beat a higher bidder with a generic one. The network is optimizing for its own revenue per pageview, which rewards ads people are actually likely to click.
- The winning ads render into the widget, typically several at once filling out the recommendation grid alongside genuine editorial recommendations from the publisher.
- Your click (or lack of one) feeds back into the system, refining the predicted CTR for that ad, that context, and often that specific reader going forward.
What actually drives the ranking#
Contextual signals matter most for first-time or logged-out readers. Without much behavioral history, the network leans on contextual targeting, matching an ad's category to the article's topic. A personal finance article is more likely to surface a finance or insurance ad than a random home goods ad, because that pairing has historically performed better across the network's whole dataset.
Behavioral signals take over as you build a browsing history. If the network's cookie or device ID has seen you click travel ads before, travel advertisers become more competitive for your impressions specifically, even on an unrelated article page. This is closer to how a demand-side platform targets audiences in broader programmatic buying.
Device and geo filter the eligible pool before ranking even starts. An advertiser targeting only mobile users in a specific country never enters the auction for a desktop reader elsewhere, regardless of bid.
Predicted CTR is model-driven and constantly updated. Each network runs its own machine learning models estimating how likely a given ad is to be clicked by a given reader in a given context. This prediction, not the raw bid, is usually the bigger factor in who wins, which is why a well-crafted headline and image can outperform a much larger budget.
Frequency and freshness caps affect what's eligible. Networks generally avoid showing you the exact same creative repeatedly in a short window, both to protect the reader experience and because a stale, over-shown ad's predicted CTR naturally decays. This is part of why advertisers rotate multiple ad creative variants inside one campaign.
Where header bidding and supply paths fit in#
On networks that resell inventory through broader programmatic pipes, more than one demand source can compete for the same widget slot simultaneously, a setup similar to header bidding in traditional display. The supply-side platform managing the publisher's inventory may route a single ad request to several potential buyers before the widget renders. This is one reason the native ad supply chain can involve more intermediaries than a simple "advertiser pays publisher" model suggests, and why the same slot can be filled by different networks' demand depending on the moment.
This resold-inventory layer is also why identifying which network actually served an ad you're looking at isn't always obvious from the surface. A widget branded as one network's placement can, in practice, be filled by demand routed in from a partner. If you're doing competitive research and the network attribution matters to your analysis, it's worth reading past the widget's visible branding to confirm the actual serving path, which is exactly the kind of detail a supply-chain trace is built to surface rather than something you can eyeball from the page alone.
What this means for advertisers trying to win more auctions#
Since predicted CTR carries so much weight, a few practical levers move your odds of winning the slot without simply raising your bid:
- Match the creative to the placement's likely context. An ad angle that reads naturally next to editorial content, rather than looking like an obvious interruption, tends to earn a higher predicted CTR because it more closely resembles what the reader came to the page for.
- Run multiple creative variants inside one campaign. Since the model's prediction is specific to each creative and context pairing, a single ad limits you to one data point. Several variants let the algorithm find which one performs best for which audience segment, and let you retire the ones it doesn't favor.
- Refresh creative before performance decays. Because frequency and freshness affect predicted CTR, an ad that was winning consistently a month ago can quietly lose auctions today simply from overexposure to the same audience, even with an unchanged bid.
- Target tightly rather than broadly. A campaign eligible for every geo and device dilutes its own average predicted CTR by competing in contexts where it doesn't perform well. Narrowing eligibility to where the creative actually resonates raises its win rate in the contexts that matter.
- Watch what's already surviving the auction repeatedly. An ad still live after several weeks on a given network has, by definition, kept winning enough auctions to justify its advertiser's continued spend. That's a stronger signal of what the model rewards than any theory about the algorithm.
Why the same article shows different ads to different readers#
If you and a colleague both open the same article at the same time, you'll often see different ads in the widget. That's expected, not a glitch. Different geo, device, browsing history, and even the specific millisecond the auction runs can all shift which candidate wins. Publishers benefit from this personalization because it raises the average predicted CTR across their whole audience, which is the actual metric the algorithm is optimizing.
How OpenAdLibrary helps#
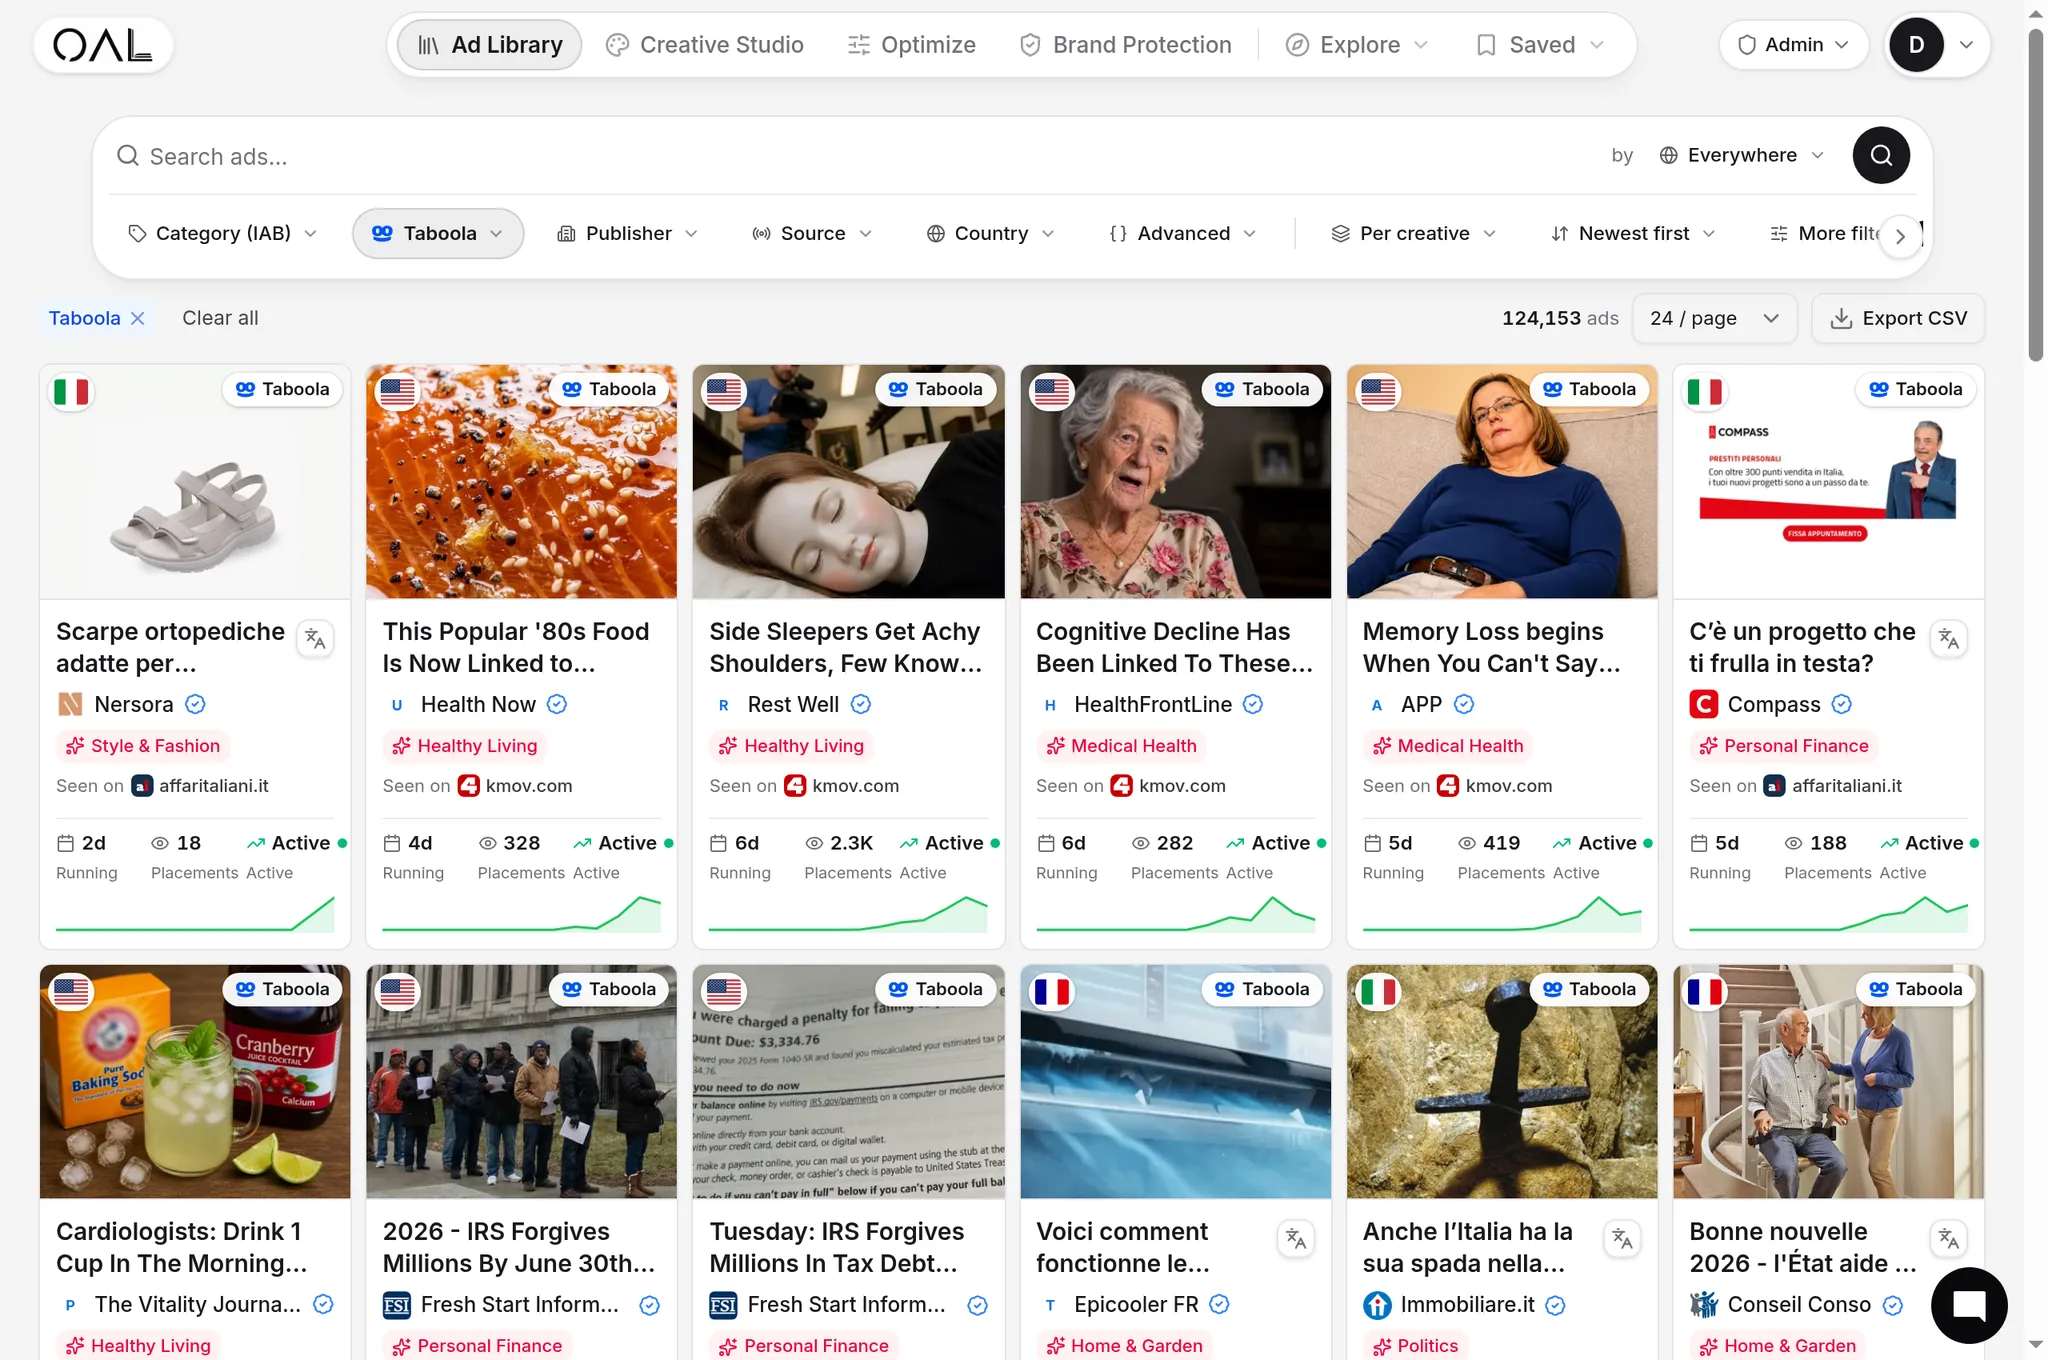
Since the algorithm rewards creatives with strong predicted engagement, studying what's already winning that auction repeatedly, meaning ads that have stayed live for weeks, is one of the most direct ways to reverse-engineer what a given network's model rewards. OpenAdLibrary's ad intelligence tools let you filter by network, vertical, and longevity to see which creatives keep clearing that bar in production, rather than guessing at what the model prefers.
The short version#
A recommendation widget's ad slot is won by a real-time auction that weighs bid and predicted engagement together, refreshed by contextual and behavioral signals on every single page load. Understanding that combination, rather than assuming it's a simple highest-bidder auction, is the difference between writing creative that merely bids well and creative the algorithm actually wants to show.
It also explains a pattern that trips up a lot of advertisers new to the channel: a campaign that performed well for the first week and then quietly slid in delivery, without any change to the bid. Nothing broke. The predicted CTR that made the creative competitive simply decayed as more of the eligible audience had already seen it, and the auction started favoring fresher candidates instead. Treating that decline as a signal to refresh creative, rather than a signal that the network or the offer stopped working, is usually the right read.