Español
 Português (Brasil)
 Français
 Deutsch
 Italiano
 Nederlands
 Polski
 Svenska
 Türkçe
 Русский
 日本語
 한국어
 简体中文
 Tiếng Việt
 Bahasa Indonesia
 繁體中文
 Čeština
 Dansk
 Norsk (bokmål)
 Suomi
 Ελληνικά
 Română
 Magyar
 Українська
 ไทย
 हिन्दी
 العربية
 עברית
Building a Competitive Ad Intelligence Workflow (Watchlist to Action)
Most teams check competitor ads once a quarter and call it research; a real intelligence workflow runs every week with a scoped watchlist, a fixed cadence, a creative scoring rubric, and a clean handoff into media buying.

Most "competitor ad research" is really ad archaeology. Someone exports a batch of screenshots before a quarterly planning meeting, the deck gets a round of nods, and nobody opens the folder again for three months. By then the creatives that mattered have already been scaled, milked, and retired. You studied a graveyard.
A competitive intelligence workflow fixes that by turning a one-off project into a standing system. It is not more dashboards or a bigger saved-ads folder. It is four connected stages that run on a clock: a watchlist that defines what you watch, a collection cadence that defines how often, a scoring rubric that decides what deserves attention, and an action handoff that pushes findings into media buying. Get those four working together and you stop reacting to competitors a quarter late.
This guide builds the system end to end. It assumes you already know why you spy. If you are starting cold, read the pillar How to Spy on Competitor Ads in 2026 (Native, Display & Social) first, then come back to operationalize it.
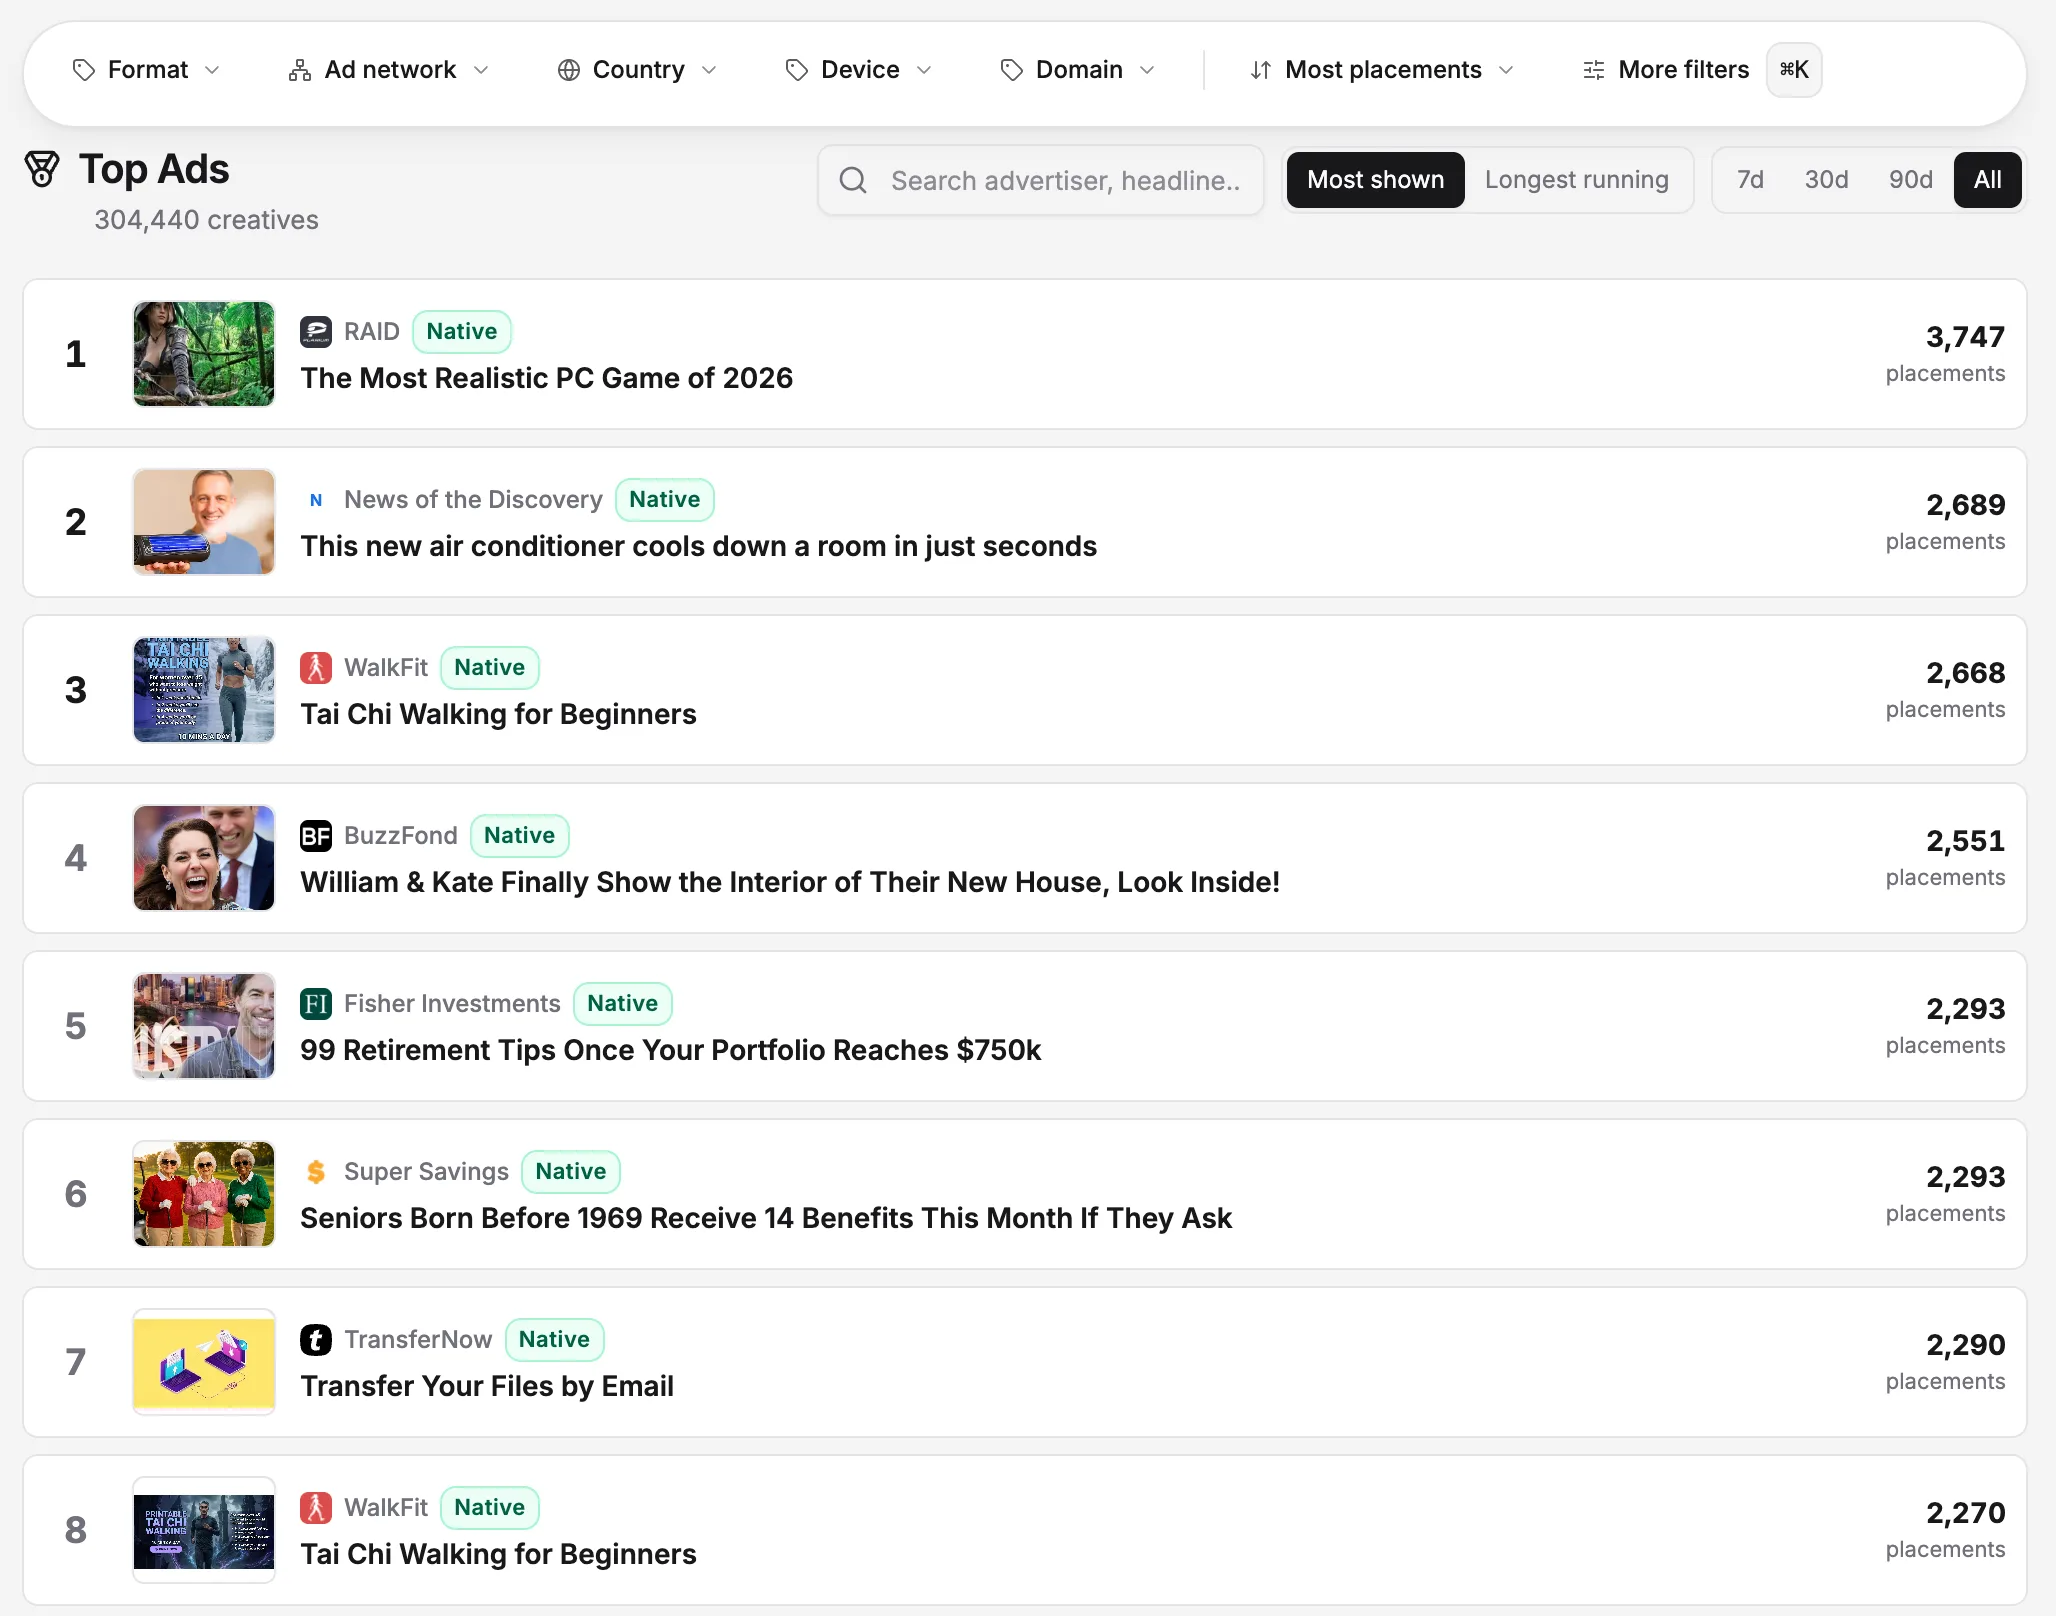
To set the scale of the problem: OpenAdLibrary describes its library as millions of Meta, TikTok, Google and native ads, many of them observed repeatedly. No human checks that by scrolling. A workflow is the only way to read a haystack that size and pull out the few items that change a buying decision.
What a competitive intelligence workflow actually is#
A competitive intelligence workflow is a repeatable system for monitoring competitor advertising on a fixed cadence instead of ad hoc. Four moving parts: a scoped watchlist, a collection rhythm, a creative scoring rubric, and a defined handoff into media-buying decisions. The goal is continuity. You want to catch moves as they happen, not assemble a snapshot after they are already over.
The shift is from project to process. A project has a start, an end, and a document. A process has a cadence and produces decisions, week after week, with context that compounds. In competitive intelligence terms, you are building a monitoring loop, not writing a research report.
The four stages map to four questions you should be able to answer at any moment:
| Stage | Question it answers | Output |
|---|---|---|
| Watchlist | Who and what am I tracking? | A scoped list of advertisers and offers |
| Cadence | How often do I look, and how? | A weekly rhythm plus an alert layer |
| Scoring | What deserves my attention? | A ranked shortlist of creatives |
| Action | What do I do about it? | Tests, briefs, defensive moves |
Skip any one and the system leaks. No watchlist and you drown in noise. No cadence and you drift back to quarterly. No scoring and every ad looks equally urgent. No action handoff and you have built an expensive hobby.
Stage 1: Define the watchlist (scope before you scale)#
The instinct is to track everyone. Resist it. A watchlist of 40 advertisers you glance at is worth less than 8 you actually understand. Scope tightly, then expand only when the cadence has spare capacity.
Build your watchlist in three tiers:
- Direct rivals. The 3 to 6 advertisers selling the same offer to the same audience. These get the deepest attention. You want their full creative rotation, not the highlights.
- Category leaders. The 2 to 4 advertisers that appear most often in your vertical, even if they are not direct competitors. Public captures do not show spend, so judge "leader" by how much of the category's creative you see from them. Their long-running creatives are angles worth studying, not pre-validated winners.
- Wildcards. 2 to 3 aggressive newcomers or adjacent-vertical advertisers whose angles tend to bleed into yours. This is where genuinely novel hooks show up before everyone copies them.
For each entry, record more than a brand name. Note the specific offers you care about (a competitor may run five products; you care about one), the networks they buy on, and the geos that overlap with yours. A competitor with a heavy tier-1 native presence but no presence in your market is context, not a threat. Tag it that way.
Your vertical sets where to point the watchlist. If you sell in a category where many advertisers run similar hooks, a sloppy watchlist will bury you in lookalikes. Here is a finance ad captured in June 2026, the kind of deadline-driven hook that can reappear around tax deadlines:

The discipline that separates a useful watchlist from a bloated one: every advertiser you add needs an owner and a reason. If you cannot say in one sentence why a name is on the list and what you would do if they made a move, it does not belong there yet.
Watchlist construction has enough nuance to deserve its own treatment. The mechanics of finding the right advertisers, deduplicating brand variants, and structuring tiers are in How to Build a Competitor Watchlist for Ad Monitoring. The key principle for the workflow: your watchlist is a living artifact. Prune dead entries monthly, promote wildcards that prove relevant, and never let it grow faster than your cadence can absorb.
Stage 2: Set the collection cadence (continuous, not quarterly)#
Here is where most workflows die. Manual collection, opening each competitor, scrolling, screenshotting, is so tedious that people quietly stop after a few weeks. The fix is not more discipline. It is removing the manual hunt entirely.
Run three loops at three speeds:
- The alert layer (between reviews). Use whatever tells you what changed so you do not have to check by hand each day: saved searches you re-run, a saved group of competitor domains, or alerts if your tool offers them. In OpenAdLibrary, the Founders plan lets you save a search, save competitors as a domain group you can apply as a one-click filter, sort by newest or longest running, and review new advertisers and activity spikes. Change between reviews is the part that matters.
- The weekly pass (operational). Once a week, 30 to 45 minutes, you review what the alert layer surfaced, score the new creatives (Stage 3), and queue actions. This is the heartbeat of the system and the cadence active media buyers should treat as non-negotiable. The mechanics of a tight weekly session are laid out in Competitive Intelligence for Media Buyers: A Weekly Research Routine.
- The monthly review (strategic). Once a month, zoom out. Which advertisers appear to be scaling overall? Which angles are emerging across the category? What has stopped appearing? This is where you adjust the watchlist itself and feed insight to creative strategy rather than to individual campaigns.
Why continuous beats quarterly is practical: native creative rotates, and the window where you can watch a creative go from first sighting to wide distribution can be days rather than months. Quarterly research can miss most of that life cycle. A weekly cadence, with an alert layer if your tool has one, catches more of it.
And here is a caution you rarely see in the "spy on your competitors" listicles: a fixed run length is not a marker of a winner. The "90-day winner" is industry lore, and we have no evidence that any run length marks one. In a June 2026 snapshot, our index spanned up to roughly 28 days of unbroken capture per creative, and the longest continuously observed creatives reached about 28 days, so no ad could show a longer run than that window. Among the ads observed at the 26-to-28-day mark were SmartAsset's IRA tax hook on Outbrain, Hidden Hearing's "next-gen hearing aids" on the Microsoft Audience Network and a group of My IQ quiz creatives. They are good ads to study because they stayed in rotation, but staying in rotation does not show spend, conversions or profit. This SmartAsset finance ad was observed running for 28 straight days in June 2026:

This is also where platform-native libraries fall short as a primary source. Meta's and TikTok's ad libraries, and the public ad repositories that designated very large platforms must maintain under Article 39 of the EU Digital Services Act (the regime under which, on 5 December 2025, the Commission fined X €120 million in a single decision covering three breaches, one of them the transparency of its advertising repository), are genuinely useful but partial. Each covers only its own platform, and Taboola, Outbrain/Teads, MGID and Revcontent are not designated very large platforms, so native networks sit outside them. A workflow that depends only on them has blind spots exactly where native media buyers operate. The native side, Taboola, Outbrain, MGID, needs dedicated tooling, covered in How to Spy on Competitor Native Ads (Taboola, Outbrain, MGID).
The native gap is real. Ads on Taboola, Outbrain and MGID sit outside the platform libraries most teams treat as the whole map, so a team that relies only on those libraries sees none of them. OpenAdLibrary's library covers Meta, TikTok, Google Ads and native networks. For native ads it captures the creative, classifies the supply chain behind it and follows the redirect trail to the landing page. On the Founders plan you can save searches and groups of competitor domains and re-run them on your cadence, so collection becomes a saved search rather than a manual hunt. The free plan shows the 20 newest Meta, TikTok and native ads.
Stage 3: Score creatives (signal over volume)#
By Stage 3 you have a stream of new creatives every week. Most are noise. The job is to rank them so you spend judgment only on the ones that carry signal. Eyeballing does not scale and is not consistent. A fixed rubric does both.
Score every creative on three weighted dimensions. The weights are an illustrative starting point, not a validated model, and the score ranks what to study first, not what is working:
- Observed longevity (40%). How many days the ad was observed running, from first seen to last seen. A long observation is a reason to look closer, not proof of profit: brand campaigns, testing budgets, slow optimisation and fixed contracts can keep weak ads running, and gaps in capture can shorten or stretch the span. Two days observed tells you little yet.
- Observed spread (35%). How many distinct publishers and placements the ad was observed on. In OpenAdLibrary the placement count grows each time the same creative is seen again on a later crawl, so it reflects how often and where we saw the ad as well as how widely it ran. Wide spread means the ad was delivered widely; it does not show that the buyer is funding it profitably. An ad with narrow spread may be early, tightly targeted or under-sampled; one with wide spread is a stronger candidate for study, not a confirmed winner.
- Scaling recency (25%). Is observed spread increasing in your most recent captures? A creative that jumped from 5 to 40 observed placements between two weekly reviews is being delivered more widely, which makes it the freshest observation you can get. Capture coverage and network delivery changes can also move the count, so confirm it before you act.
Turn the weighted score into three tiers and act only on the top two:
| Tier | Profile | Action |
|---|---|---|
| A, priority study | High observed longevity plus wide observed spread | Reverse-engineer the funnel, brief a test of your own version |
| B, emerging | Short observed longevity plus rising spread | Watch closely, flag for next week |
| C, low priority | Low longevity, narrow, flat | Log and revisit |
The rubric is a way to decide what to study first, not a measure of results. What an advertiser runs is more informative than what it says about itself, which is the core logic of practical ad intelligence. But public captures show what ran, where and when. They do not show budget, conversions or profit, and ads can keep running without converting, for brand goals, testing, contracts or because nobody has switched them off.
Look at the two ads below as a scoring exercise. The first, a hearing-device ad, had been observed running for 26 days when captured. The second, a "side sleeper" sleep-aid hook, had been observed for 14 days. Under this rubric both would get a closer look. Creatives first seen only 0 to 3 days earlier are Tier C: log them and revisit once they have a longer record.


For Tier-A creatives, scoring is just triage. The real value comes from tracing the click through to the advertiser's landing page and pre-lander, so you can see what the funnel looks like and form hypotheses about why it might convert. The step-by-step method is in Reverse-Engineer a Competitor's Native Ad Funnel (Creative to Landing Page). Following a long-running ad to its funnel does not mean clicking live ads in the wild: OpenAdLibrary follows the redirect responses for native ads and stores the redirect trail and captured landing page, and the Founders plan adds real-advertiser resolution. Doing it by hand means careful, sandboxed tracing.
Stage 4: Feed it into media buying (the handoff)#
Intelligence that does not change a buying decision is overhead. The final stage is the handoff: a defined path from "we found this" to "we did something." Without it, your beautifully scored shortlist dies in a spreadsheet.
Four concrete outputs, each tied to a tier:
- Test briefs (from Tier-A creatives). A competitor angle you have seen persist becomes a hypothesis. Do not copy the creative. Extract the mechanism (the hook, the offer framing, the pre-lander structure) and brief your own version. Adaptation, not duplication, avoids lifting another advertiser's assets and gives you something you can test on your own audience. This is bread and butter for affiliate marketing teams who live or die by creative velocity.
- Angle backlog (from Tier-B plus the monthly review). Emerging hooks that are not proven yet go into a ranked backlog. When a current campaign fatigues, you pull from a vetted list instead of staring at a blank page.
- Defensive moves (from competitor scaling). When a direct rival's ads show up on more of the audiences and placements you buy, that may mean a larger buy, although captures do not show budget. Treat it as a prompt to check your own auction costs, then decide deliberately whether to contest, cede, or flank, rather than discovering the pressure in your rising costs weeks later.
- Creative refresh triggers (from longevity decay). When a competitor's long-running creative drops in observed spread or disappears from captures, the angle may be fatiguing, the budget may have moved, or the capture may have missed it. Check your own results for signs of fatigue before you queue a refresh.
Home and garden is a good example of where timing matters, since seasonal subsidy and energy angles can spike and fade quickly. This solar-battery ad was observed running for 27 days in June 2026. In a category that swings with weather and policy news, that is worth noting, but it does not show that the offer was converting:

To make the handoff stick, give every workflow run a single artifact the buying team reads: top three Tier-A creatives, what to test, any defensive flags. One page, every week, same format. Consistency is what gets it read.
For teams that want to keep more of the loop in one place, OpenAdLibrary's Creative Studio can turn a finding into creative of your own (the manual editor is free; AI generation and publishing are on the Founders plan), and Copy DNA, on the Founders plan, summarises recurring headlines, calls to action and themes in captured ads. Neither tells you whether a competitor's ad worked. The companion process for turning these findings into a documented competitor picture is in How to Find Out What Ads Your Competitor Is Running (Step by Step).
Putting the loop together#
Here is the whole system on one timeline:
- Between reviews: re-run saved searches and competitor domain groups, and use alerts if your tool offers them, to catch new or widely placed creatives.
- Weekly (45 min): review what changed, score new creatives on observed longevity, spread and scaling, produce the one-page brief, queue tests and defensive moves.
- Monthly (2 hrs): category zoom-out, prune and promote the watchlist, feed strategy and the angle backlog.
- Always: every Tier-A finding traces to the advertiser, the landing page, and a decision.
The compounding payoff is context. In month one you see creatives. By month three you may see patterns: which competitors appear to test cautiously versus spray and pray, which angles recur seasonally, how long the creatives you track tend to stay in rotation. That accumulated pattern recognition is the real moat, and it only exists if the loop ran every week without you re-deciding to do it.
Why an affordable platform changes the math#
Continuous monitoring is easier to sustain when a tool's cost is small next to the decisions it informs. When a research tool feels expensive, small teams drift back to the quarterly-screenshot habit because weekly use is hard to justify. The economics quietly enforce a bad cadence. Compare each vendor's current pricing page before you choose an ad intelligence platform.
OpenAdLibrary's pricing is built around that problem. The free plan shows the 20 newest Meta, TikTok and native ads with ad detail and, for native ads, the supply chain, redirect trail and captured landing pages, no card needed. The Founders plan ($29.99 a month) adds search and every filter (including days running and last seen), saved research, real-advertiser resolution for native ads, Creative Studio AI and publishing, and the REST API and hosted MCP server. A predictable monthly cost makes it easier to run the loop weekly. The workflow above is only as good as your willingness to run it on schedule.
Start free to see the newest ads, then put your first five competitors on a watchlist (saved research and domain groups are on the Founders plan). The discipline is yours; the saved searches, the observed longevity and spread, and your weekly review are what turn that discipline into a system that compounds.
Sources: European Commission, The Digital Services Act; European Commission, Commission fines X 120 million euros under the Digital Services Act.